

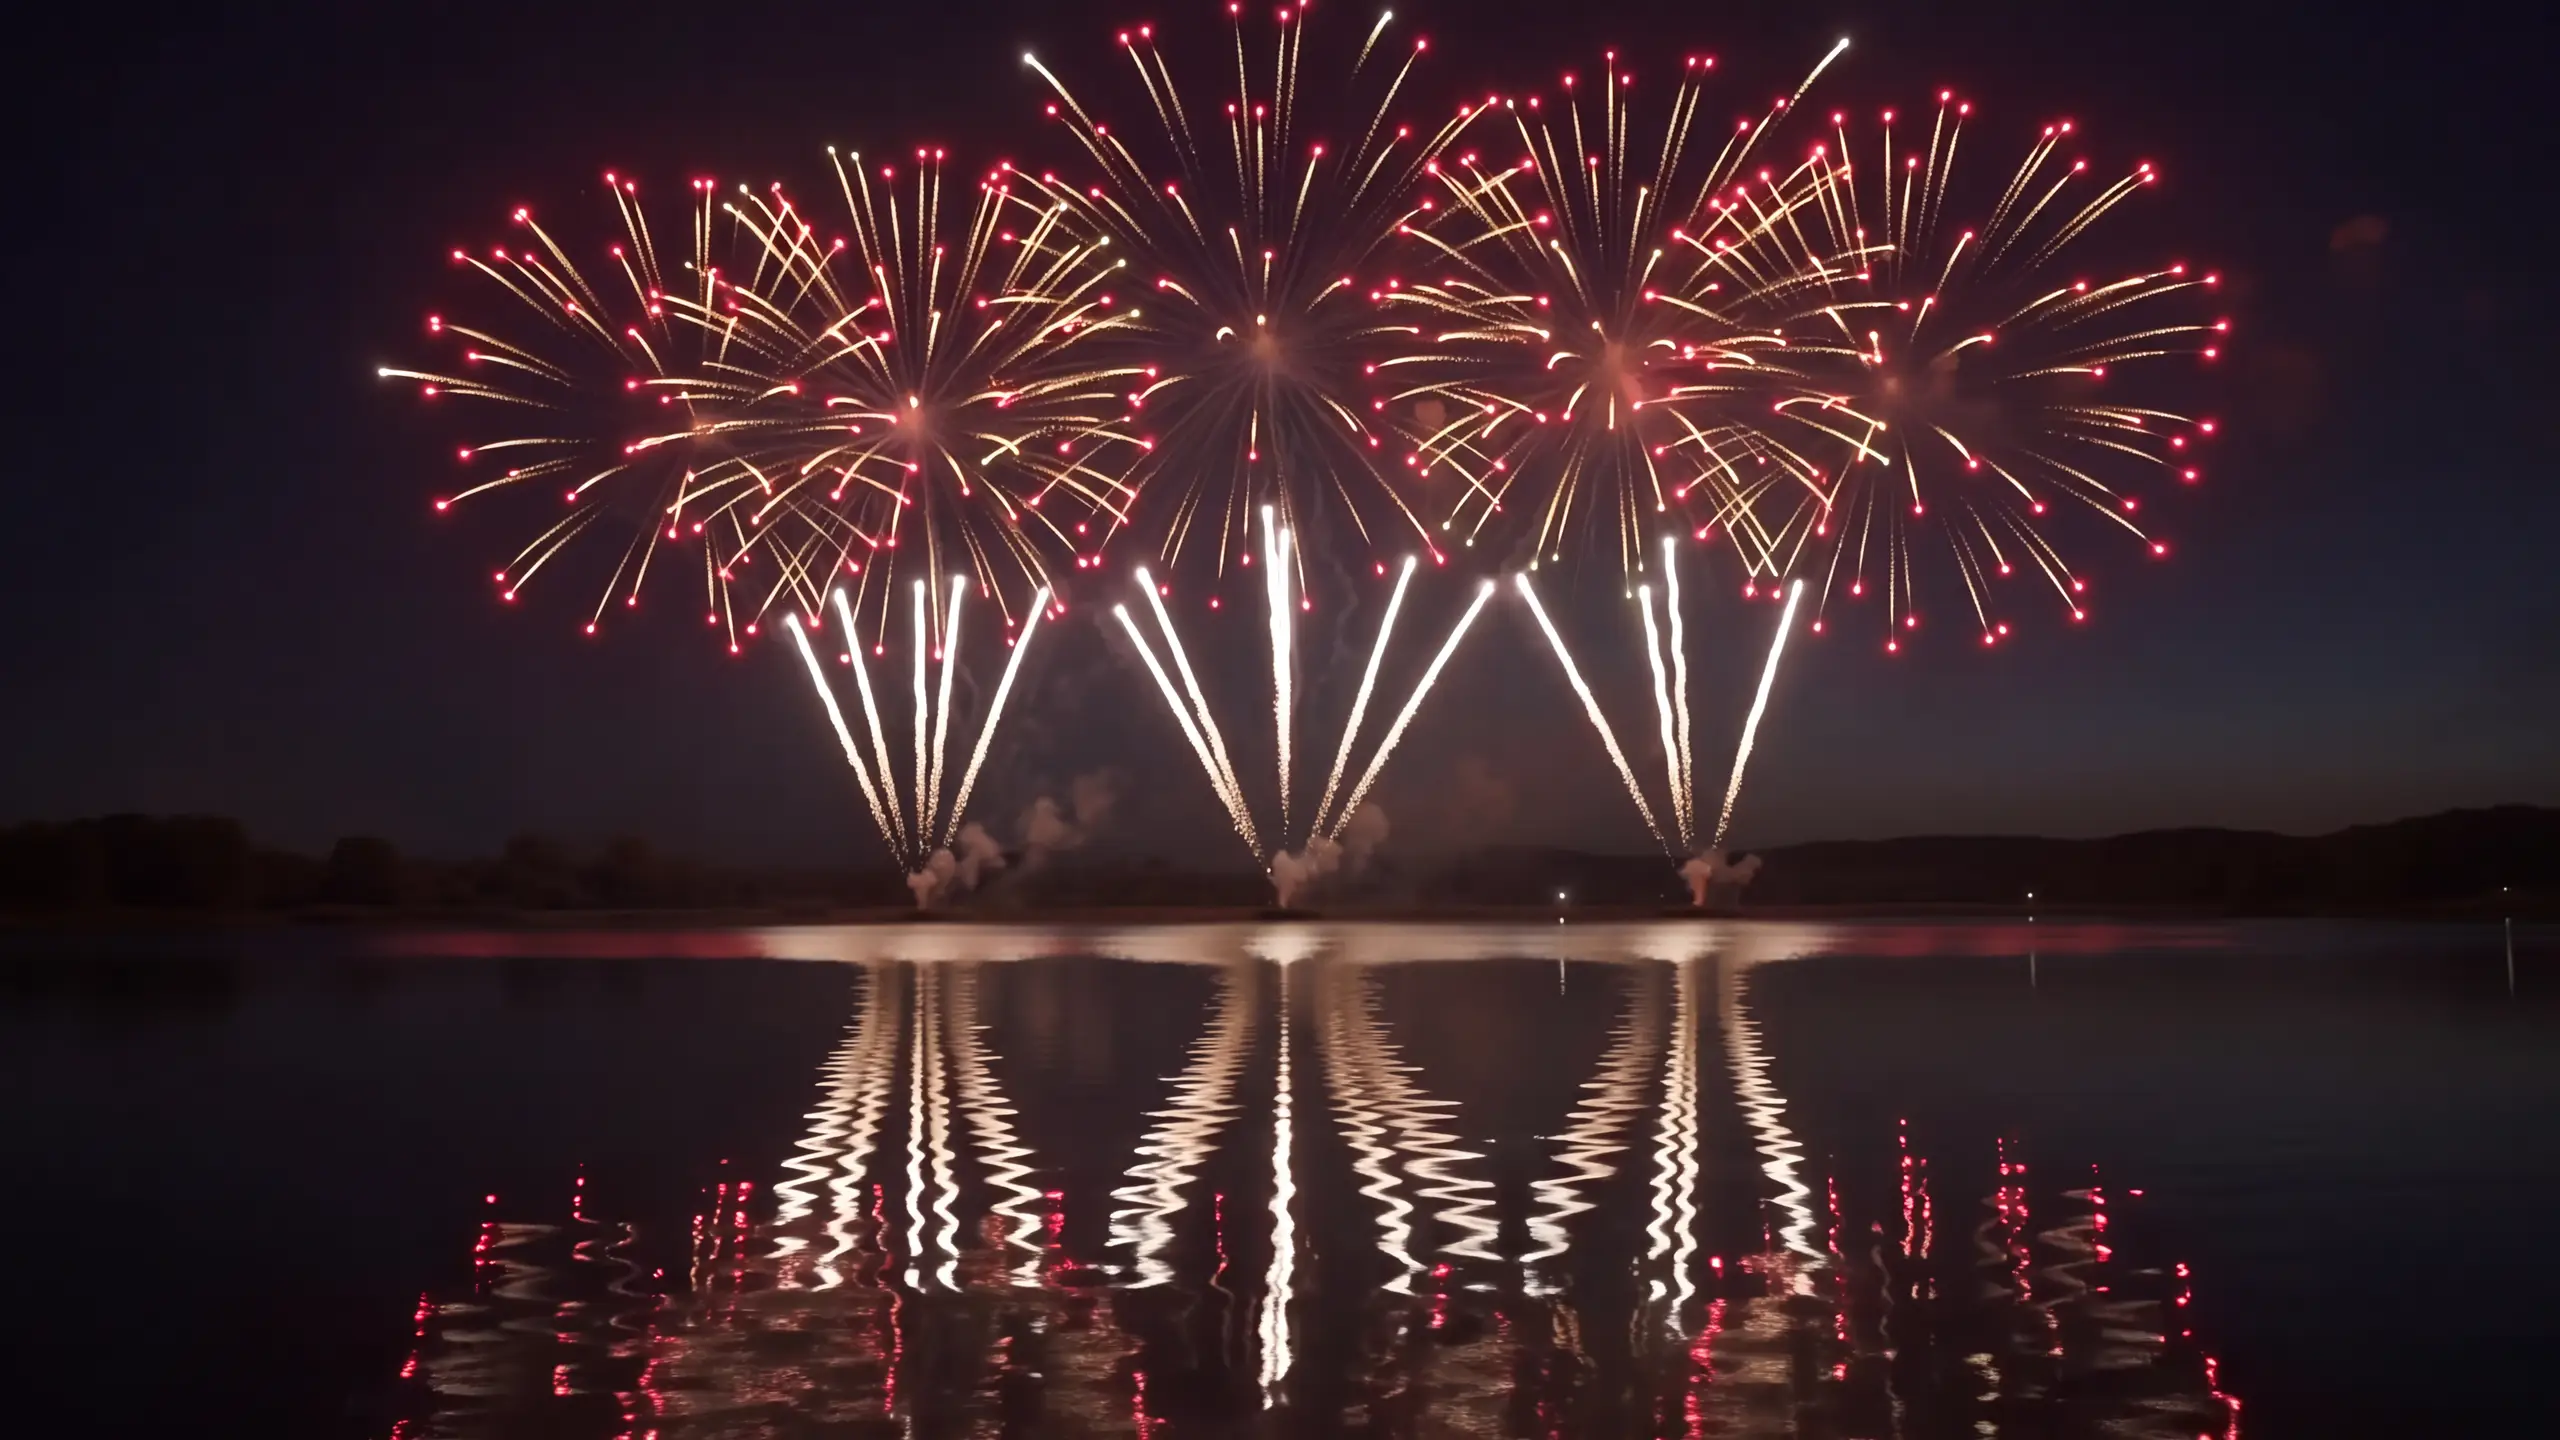
Gemini Omni Flash 1.1 API: access, pricing and code
Summary
Runway Dev gives you the official Gemini Omni Flash 1.1 API from Google. Gemini Omni Flash 1.1 is Google’s multimodal video model: it generates clips with native audio from a text prompt, from a first and a last frame or from image and video references, and it extends or edits clips you already have. This page covers access, pricing, inputs and code, and how your coding agent can build the integration for you.
What is Gemini Omni Flash 1.1?
Gemini Omni Flash 1.1, also written Gemini Omni 1.1 Flash, is Google’s video generation and editing model. It reads text, images and video together and returns a clip of 3 to 10 seconds with audio generated in the same pass: dialogue written into the prompt, sound effects and the sound of the scene.
Prompt
Locked-off wide shot of a railroad crossing on a country road at dusk. The red signal lights start flashing and the barrier arm lowers, then a long freight train rushes through from left to right, its headlight sweeping the road. Audio: the crossing bell ringing, the train horn blaring as it approaches, the roar and clatter of the wagons.Google released it on August 27, 2026. It generates the motion between a first and a last frame, takes its subject and style from reference images and clips, continues a clip you already have and edits one from a text instruction. Output comes at 360p, 720p, 1080p and 4K, the smallest being a low-cost draft size for previews.
What are the ways to use Gemini Omni Flash 1.1 on Runway Dev?
Gemini Omni Flash 1.1 runs on Runway Dev three ways, all from one account:
| Way in | Best for | What you need |
|---|---|---|
| Playground | Trying a prompt, then copying the request as code | A Runway Dev account |
| API and SDKs | Calling Gemini Omni Flash 1.1 from your own code | An API key, plus the Node or Python SDK if you want one |
| Coding agent | Having Claude Code, Codex or Cursor build the API integration into your product, tool or pipeline | The Runway Dev MCP and skills, and an API key for live calls |
Gemini Omni Flash 1.1 is also available in Model Router, a saved config you send with the request instead of a model ID. You set what to optimize for (cost, quality or latency), a maximum cost per generation and the models allowed, and the router picks one for each request sent to POST /v1/generate/video.
How do you get API access to Gemini Omni Flash 1.1?
You get API access to Gemini Omni Flash 1.1 with a Runway Dev account and an API key:
- Create an account at https://dev.runway.com.
- Create an API key in your project’s dashboard.
- Add credits to your project’s balance.
- Store the key in your environment as
RUNWAYML_API_SECRET. - Send a request with
"model": "gemini_omni_flash_1.1"and theX-Runway-Versionheader to one of its endpoints. The code below is ready to run.
How much does the Gemini Omni Flash 1.1 API cost?
The Gemini Omni Flash 1.1 API on Runway Dev is billed per second of the video it makes, at a rate set by the output size: 10 credits ($0.10) per second at 720p, the default size, with a lower rate for the draft size and higher ones for the two largest.
| Resolution | Credits | USD |
|---|---|---|
| 360p | 3.4 credits per second | $0.034 per second |
| 720p | 10 credits per second | $0.10 per second |
| 1080p | 15 credits per second | $0.15 per second |
| 4K | 30 credits per second | $0.30 per second |
- Each reference image: +1 credit ($0.01).
- Input video: +1 credit ($0.01) per second of input video.
- Each generation rounds up to a whole credit.
- A 5-second clip costs 17 credits ($0.17) at 360p, 50 credits ($0.50) at 720p, 75 credits ($0.75) at 1080p or 150 credits ($1.50) at 4K.
Prices current as of October 22, 2026. 1 credit = $0.01.
Prompt
Locked-off close shot of waves washing over a beach of smooth black volcanic pebbles at sunset, white foam spreading between the stones and draining back, the wet pebbles glistening. Audio: the wave breaking, then the rattle of pebbles as the water drains back.How the billing works:
- Sound comes with every clip at the same rate. Audio is generated each time, and there’s no audio option or separate audio price.
- Images add a charge per image, references and keyframes alike: on image-to-video, the first frame and the last frame each count as one.
- Input video is billed per second, on top of the output: the clip you extend, edit or use as a reference.
- A
durationofautois billed as 10 seconds up front, and what the clip doesn’t use is refunded once it finishes. An edit is billed on the length of its source clip instead. - An extension is billed for the footage it adds. The file it returns holds your clip followed by the new footage, and
durationsets only the new part. - Extend and edit render at 720p, so they’re billed at that rate.
- A task that fails input moderation (
SAFETY.INPUT.*) is still charged. See task failures for what each failure means.
Every rate is also listed on dev.runway.com/pricing and in the docs pricing guide.
What inputs does Gemini Omni Flash 1.1 accept?
Gemini Omni Flash 1.1 needs a prompt of up to 4,000 characters on every endpoint and takes a duration of 3 to 10 seconds or auto. Images and clips go in as frames, as references or as the video to work on, and each endpoint uses them its own way.
On POST /v1/text_to_video the prompt describes the picture and the sound together. A request can add up to 5 images and 3 videos as references, images in references and clips in referenceVideos, to set who or what appears and how it looks.
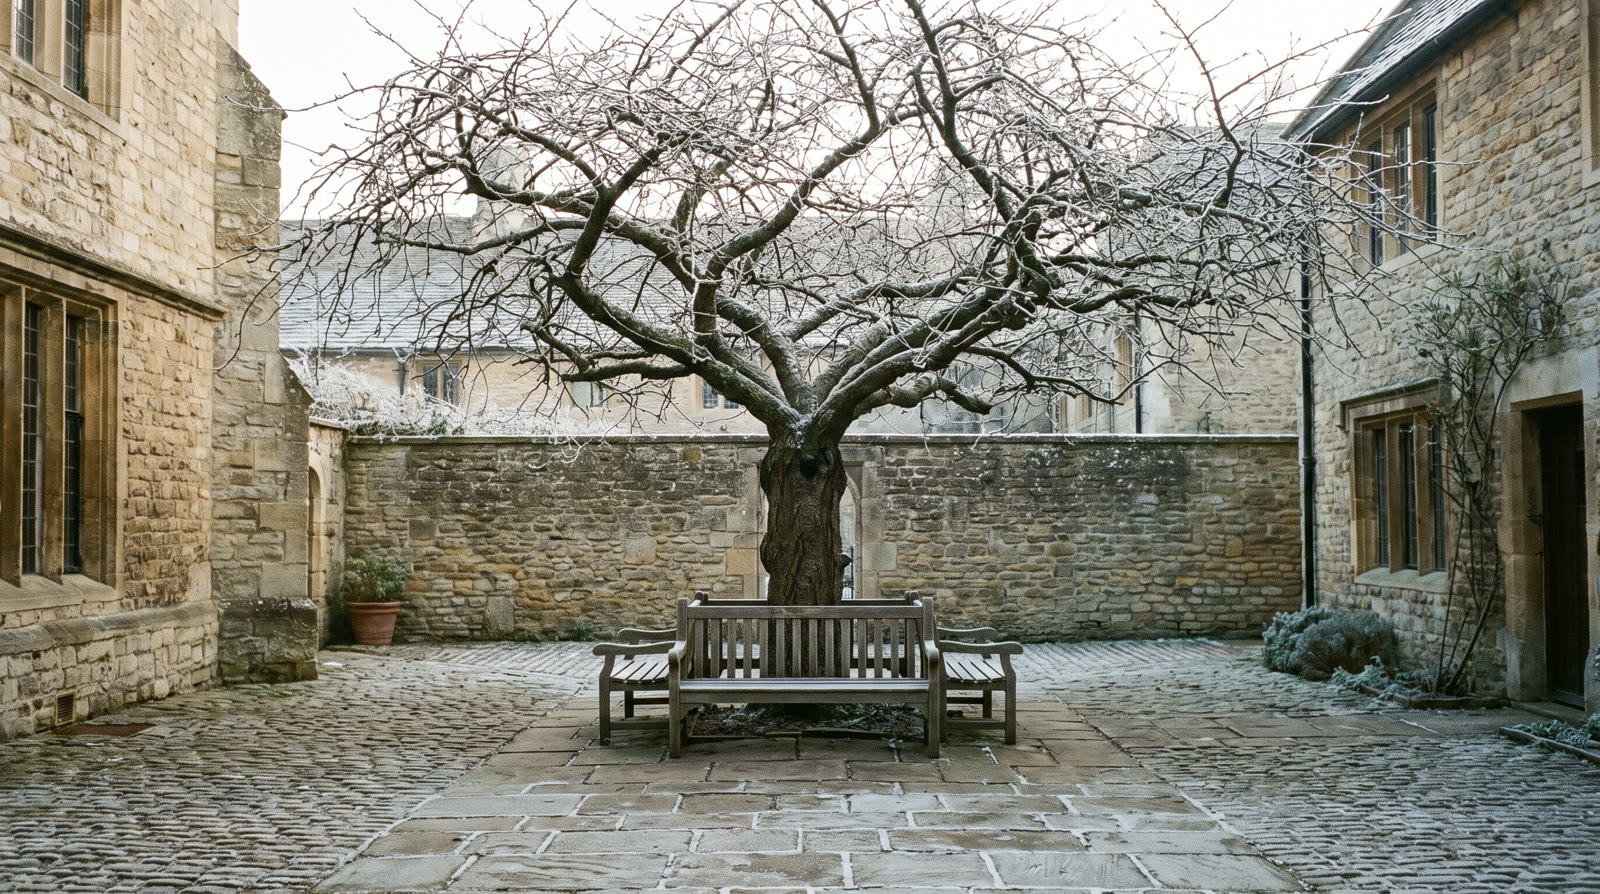
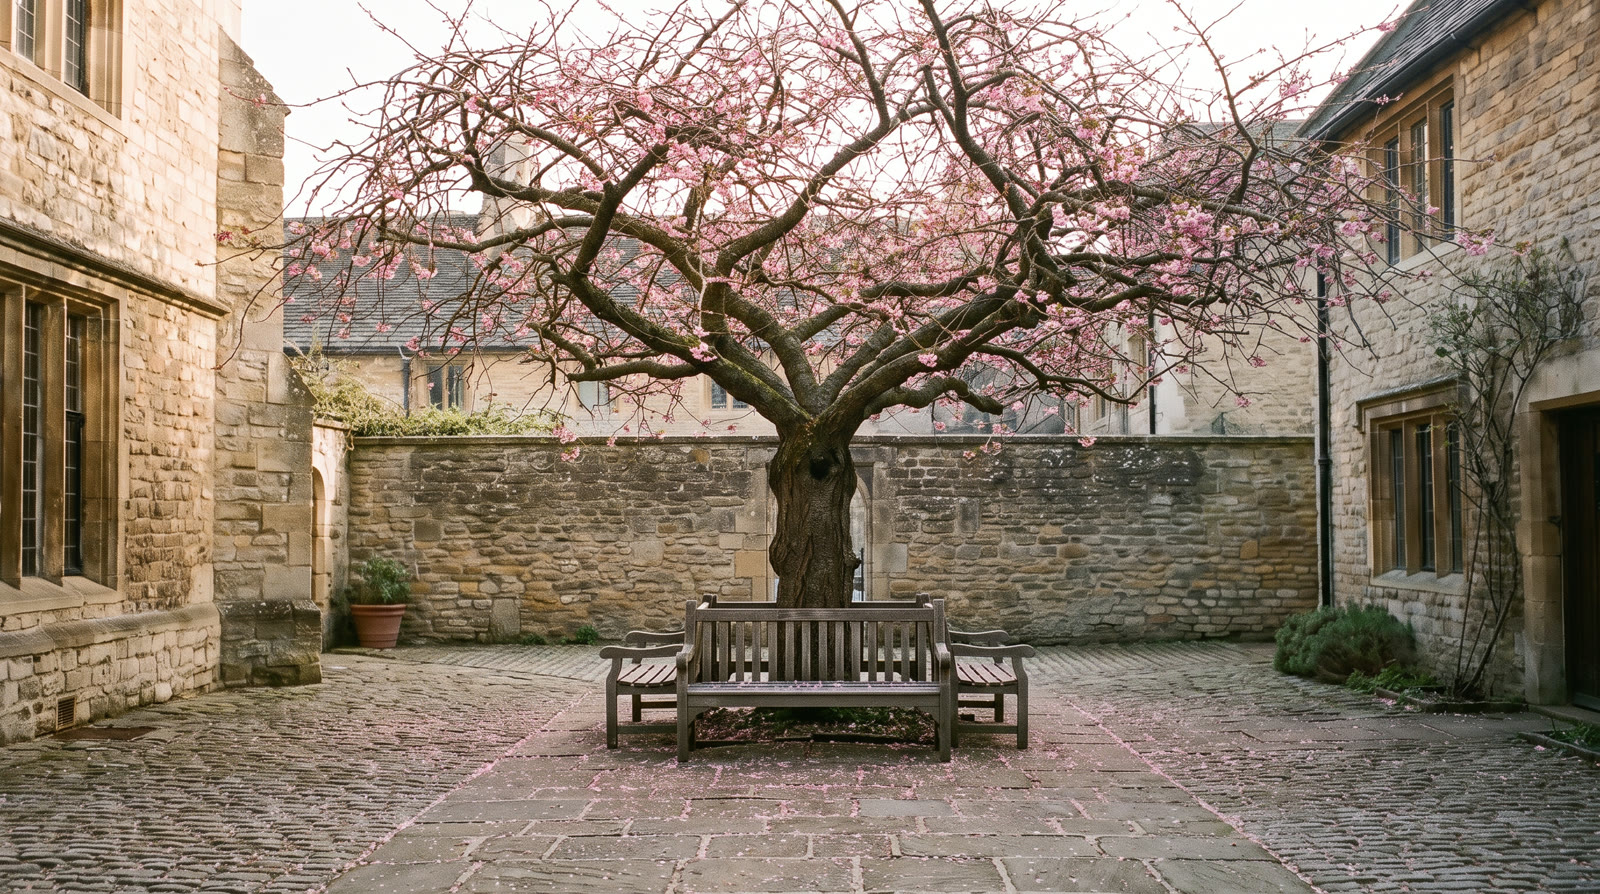
On POST /v1/image_to_video you set the opening frame, and the closing one if you want it. A single promptImage URL is the first frame. To set both, send a list with one image whose position is first and one whose position is last, and Gemini Omni Flash 1.1 generates the motion between them. A last frame on its own is rejected.
Inputs
 First frame
 Last frame
Prompt
Time-lapse from winter to spring from a fixed viewpoint in the courtyard: the frost melts, buds swell on the bare branches and open into pink blossom, and petals start to fall onto the bench. Audio: wind, dripping meltwater giving way to birdsong.On POST /v1/video_to_video, mode decides what happens to the clip in videoUri. reference (the default) makes a new video guided by it, and takes a ratio and image references. extend continues the clip, with duration setting how much footage it adds. edit changes the clip in place from the prompt and returns a video as long as the source, so its duration must be auto. Extend and edit keep the input’s orientation and take no ratio, and extend takes no image references.
Prompt
The geyser erupts: a tall column of boiling water and steam shoots into the sky, holds for a moment and collapses back into the pool, steam rolling across the terraces. Audio: a deep rumble, then the roar of the eruption and the hiss of falling water.The length of the input clip depends on the mode: reference and edit take a clip of up to 10 seconds, and extend takes a clip of up to 30 seconds, so an extended clip can be extended again while it stays under that length.
Here is every field, by endpoint:
POST /v1/image_to_video
| Field | Accepts |
|---|---|
model (required) |
gemini_omni_flash_1.1 |
promptImage (required) |
One image, or a list of up to 2 images, each with an optional position of first or last |
promptText (required) |
Text, 1 to 4,000 characters |
ratio |
One of 640:360, 360:640, 1280:720, 720:1280, 1920:1080, 1080:1920, 3840:2160 or 2160:3840 |
duration |
Whole number from 3 to 10, or auto |
POST /v1/text_to_video
| Field | Accepts |
|---|---|
model (required) |
gemini_omni_flash_1.1 |
promptText (required) |
Text, 1 to 4,000 characters |
ratio |
One of 640:360, 360:640, 1280:720, 720:1280, 1920:1080, 1080:1920, 3840:2160 or 2160:3840 |
duration |
Whole number from 3 to 10, or auto |
references |
A list of up to 5 images |
referenceVideos |
A list of up to 3 videos |
POST /v1/video_to_video
| Field | Accepts |
|---|---|
model (required) |
gemini_omni_flash_1.1 |
videoUri (required) |
One video |
promptText (required) |
Text, 1 to 4,000 characters |
mode |
One of reference, extend or edit. Default reference |
ratio |
One of 640:360, 360:640, 1280:720, 720:1280, 1920:1080, 1080:1920, 3840:2160 or 2160:3840 |
duration |
Whole number from 3 to 10, or auto |
references |
A list of up to 5 images |
Images and videos go in as an HTTPS URL, a runway:// URI from an upload or a data URI; inputs lists sizes and formats. Each table shows what a field accepts on its own. Rules that combine fields are checked when the task is submitted, and the API reference has them in full.
A few rules change what you send:
ratiosets the size as well as the shape, and the size sets the price. Each value is an output size in pixels, landscape or portrait, and a request without one renders at 720p landscape.durationdefaults toauto, so the model picks the length unless you send a number.- There’s no
audiofield. Every clip has sound, and a request that sendsaudioreturns a 400. - Unknown fields return a 400. The request schema is strict, so a field name from another API, such as
aspect_ratioorresolution, is rejected rather than ignored. - Frames must fit the aspect range in inputs. A first or last frame far wider or taller than that is rejected.
How do you call Gemini Omni Flash 1.1 from curl, Node and Python?
You call Gemini Omni Flash 1.1 by sending gemini_omni_flash_1.1 as the model to one of its endpoints. This request makes a clip with sound from text with POST /v1/text_to_video, and the other fields keep their defaults:
curl
curl -X POST https://api.dev.runwayml.com/v1/text_to_video \
  -H "Authorization: Bearer $RUNWAYML_API_SECRET" \
  -H "X-Runway-Version: 2024-11-06" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini_omni_flash_1.1",
    "promptText": "Locked-off wide shot of fireworks over a calm lake at night. Rockets streak up from the far shore and burst into gold and red, their light reflected in the water, each boom arriving a moment after its flash. Audio: the whistle of the rockets, deep booms echoing across the lake, a light breeze."
  }'

# The response carries the task id. Poll the task until it finishes:
curl https://api.dev.runwayml.com/v1/tasks/$TASK_ID \
  -H "Authorization: Bearer $RUNWAYML_API_SECRET" \
  -H "X-Runway-Version: 2024-11-06"
Node.js
import RunwayML, { TaskFailedError } from '@runwayml/sdk';

// Reads your API key from RUNWAYML_API_SECRET.
const client = new RunwayML();

try {
  const task = await client.textToVideo
    .create({
      model: 'gemini_omni_flash_1.1',
      promptText: 'Locked-off wide shot of fireworks over a calm lake at night. Rockets streak up from the far shore and burst into gold and red, their light reflected in the water, each boom arriving a moment after its flash. Audio: the whistle of the rockets, deep booms echoing across the lake, a light breeze.',
    })
    .waitForTaskOutput();
  console.log(task.output);
} catch (error) {
  if (error instanceof TaskFailedError) {
    console.error(error.taskDetails);
  } else {
    throw error;
  }
}
Python
from runwayml import RunwayML, TaskFailedError

# Reads your API key from RUNWAYML_API_SECRET.
client = RunwayML()

try:
    task = client.text_to_video.create(
        model="gemini_omni_flash_1.1",
        prompt_text="Locked-off wide shot of fireworks over a calm lake at night. Rockets streak up from the far shore and burst into gold and red, their light reflected in the water, each boom arriving a moment after its flash. Audio: the whistle of the rockets, deep booms echoing across the lake, a light breeze.",
    ).wait_for_task_output()
    print(task.output)
except TaskFailedError as error:
print(error.task_details)Generation is asynchronous:
- The create request returns a task ID right away, and the video is made in the background.
- Poll
GET /v1/tasks/{id}with backoff until the status isSUCCEEDED,FAILEDorCANCELLED.THROTTLEDmeans the task is waiting in a queue, not rejected. - Output URLs are temporary, so download the video when the task succeeds. See outputs.
- The SDKs poll for you.
waitForTaskOutput()andwait_for_task_output()raiseTaskFailedErrorwith the task’s details when it fails. They also stop waiting after a default timeout while the task keeps running, so pass a longer timeout or keep polling the task ID. - To use your own rules instead of one fixed model, send a Model Router’s
configIdtoPOST /v1/generate/videoin place of the model. AdddryRunto see which model it picks without creating a task.
Why does a Gemini Omni Flash 1.1 API request fail?
A Gemini Omni Flash 1.1 request fails with a 400 when a field is wrong, and a task fails with a failure code that names the cause. The common ones:
- A 400 that names
audio,aspect_ratioorresolution: the request carries a field Gemini Omni Flash 1.1 doesn’t take on Runway Dev. Dropaudio, since every clip has sound, and set the size and shape withratio. - A 400 saying the input video is too long for its mode:
reference,extendandediteach cap the input clip. Trim it to the mode’s cap in the inputs above. - A 400 for
ratio, or for image references, in extend mode: an extension keeps the input’s orientation and takes neither. Edit takes noratioeither. - A 400 for a number in
durationin edit mode: an edit returns a clip as long as the source. Sendauto. - An image-to-video request with only a last frame: a first frame is required. Add one with
positionset tofirst. SAFETY.INPUT.*: content moderation rejected an input. The task is charged and shouldn’t be retried as is: change the inputs first.SAFETY.OUTPUT.*: the generated video was rejected by moderation. Change the prompt or references before you try again.THIRD_PARTY.INPUT_VALIDATIONon an edit that changes what someone says: Gemini Omni Flash 1.1 doesn’t process speech edits yet. Edit the picture only, or use another model for the speech.- An input file that couldn’t be decoded: re-export it in a common format, such as an H.264 MP4 or a JPEG, and try again.
THIRD_PARTY.UNAVAILABLEorTHIRD_PARTY.RATE_LIMITED: the model’s provider didn’t return the video, because of an outage or load. Wait, then retry.- An output link that stopped working: output URLs expire. Download the video when the task succeeds.
What does Runway Dev add when you call Gemini Omni Flash 1.1?
Runway Dev serves Gemini Omni Flash 1.1 next to Runway’s own models and other labs’ models, behind one API key and one credit balance: you build with a single key and pay a single bill, instead of an account, a key and an invoice per lab.
A coding agent can do the Gemini Omni Flash 1.1 integration for you on Runway Dev, end to end. Connect the Runway Dev MCP and the agent works from your live account: the models your project can call with their current prices and input limits, your credit balance and the record behind any task. It writes the integration against what the API accepts today, and when a task fails it looks up the reason and fixes it. The Runway Dev skills show the agent how to integrate with the official SDKs and how to build with models, Model Routers, Recipes and Workflows.
FAQ
How do I get API access to Gemini Omni Flash 1.1?
Create a Runway Dev account at dev.runway.com, make an API key and add credits. Then send gemini_omni_flash_1.1 as the model to any of its endpoints: POST /v1/image_to_video, POST /v1/text_to_video and POST /v1/video_to_video. To have a coding agent write the integration instead, connect the Runway Dev MCP and install the Runway Dev skills: the agent builds it from your live account, with the prices and input limits your project has today.
Can I use the Gemini Omni Flash 1.1 API without a Google Cloud account?
You can use the Gemini Omni Flash 1.1 API without a Google Cloud account: a Runway Dev account and API key are all you need. There’s no Google Cloud project, billing account or region to set up, and Gemini Omni Flash 1.1 is paid from the same credit balance as every other model on Runway Dev.
How much does the Gemini Omni Flash 1.1 API cost?
On Runway Dev, Gemini Omni Flash 1.1 costs 30 credits ($0.30) per second at 4K, 15 credits ($0.15) per second at 1080p, 10 credits ($0.10) per second at 720p and 3.4 credits ($0.034) per second at 360p, with sound included at every size. Each image adds a per-image charge and input video a per-second one, and every generation rounds up to a whole credit. Prices are current as of October 22, 2026.
Is the Gemini Omni Flash 1.1 API on Runway Dev the official model?
Runway Dev’s Gemini Omni Flash 1.1 API runs the official Gemini Omni Flash 1.1 model from Google. You call it with your Runway Dev API key and the model ID gemini_omni_flash_1.1, like every other model on Runway Dev.
Can I use Gemini Omni Flash 1.1 without writing code?
You can use Gemini Omni Flash 1.1 on Runway Dev without writing code yourself. The playground sends a request from a form and gives it back as code, and a coding agent connected to the Runway Dev MCP writes the integration for you.
Does the same Runway Dev API key work for Gemini Omni Flash 1.1 and other models?
One Runway Dev API key calls Gemini Omni Flash 1.1 and every other model your project can use, Runway’s own and other labs’, with the same SDKs, task flow and credit balance. Switching models means changing the model field, or the rules of a Model Router.
What is the Gemini Omni Flash 1.1 model ID on Runway Dev?
The model ID is gemini_omni_flash_1.1, and it is the same on all of its endpoints: POST /v1/image_to_video, POST /v1/text_to_video and POST /v1/video_to_video.
How long can a Gemini Omni Flash 1.1 video be, and at what resolutions?
A Gemini Omni Flash 1.1 clip on Runway Dev runs 3 to 10 seconds, or set duration to auto and the model picks the length. It comes out at 360p, 720p, 1080p and 4K, landscape or portrait, chosen through the ratio you send. To go longer, extend it on POST /v1/video_to_video: extend takes a clip of up to 30 seconds and adds up to 10 seconds to it.
Can Gemini Omni Flash 1.1 extend or edit an existing video through the API?
Gemini Omni Flash 1.1 extends and edits clips on POST /v1/video_to_video. Set mode to extend to continue a clip, with duration as the length to add, or to edit to change it in place from promptText. Both keep the input’s orientation and render at 720p.
Can Gemini Omni Flash 1.1 interpolate between a first and a last frame through the API?
Gemini Omni Flash 1.1 generates the motion between two frames on POST /v1/image_to_video. Pass promptImage as a list with one image whose position is first and one whose position is last, plus a promptText. A last frame on its own is rejected.
Why did my Gemini Omni Flash 1.1 request fail with SAFETY.INPUT.TEXT?
SAFETY.INPUT.TEXT means content moderation rejected an input of your request; the suffix hints at the prompt but may not match. The task is charged and shouldn’t be retried as is, so change the prompt or inputs before you send it again.
Can I switch from Gemini Omni Flash 1.1 to another video model without changing my code?
A Model Router lets you change models without touching your code. Send its configId to POST /v1/generate/video, and change the models it may use, its priority or its cost cap in the router.
Start building on Runway Dev
Related articles
 Tutorials
Choosing the right model for your use case
Why video and image models are not interchangeable, and how to set up a Model Router that picks the best model for every request.
 Concepts
Can I use AI image and video generation commercially in my product?
Provider terms, copyright, input rights, training and disclosure: what decides whether you can ship AI images and video commercially.
 Tutorials
How to build a generative media integration with your coding agent
Let a coding agent build a video, image or audio generation integration end to end, with Runway Dev MCP giving it live account access.